gron 0.7.1 turns JSON into lines of assignment statements so that grep can read it. The Windows build is a single 7050752-byte exe, and a 1072296-byte JSON file becomes 110001 lines.
The problem it solves is searching a deeply nested JSON document without knowing its shape. jq wants a path; gron gives you the path of every value in the file, one per line.
I ran it over a 1072296-byte array of 10000 records, then ran it backwards to recover the JSON, and the two directions are not symmetric at all.
One 7050752-byte exe
Single file, no installer, no runtime. Written in Go, so the whole runtime is inside the image.
| Item | Value | Note |
|---|---|---|
| Release zip | 3954441 bytes | gron-windows-amd64-0.7.1.zip |
| gron.exe | 7050752 bytes | Standalone |
| Version output | 17 bytes | Prints "gron version dev" |
| Input used here | 1072296 bytes | 10000 records |
The version string says dev
gron --version prints gron version dev, not 0.7.1, even though the release is tagged v0.7.1. The binary was built without the version stamped in, so you cannot confirm the build from the binary itself.
It takes a path or stdin
Pass a filename and it reads it; pipe JSON in and it reads that. Both produce the same output, which matters when the source is a curl response rather than a file.
1072296 bytes become 110001 lines
The output is 2790097 bytes across 110001 lines. Input was a 10000-element array of objects with five fields each.
| Metric | Value |
|---|---|
| Input bytes | 1072296 |
| Output bytes | 2790097 |
| Output lines | 110001 |
| Expansion | 2.6 times larger |
Eleven lines per record
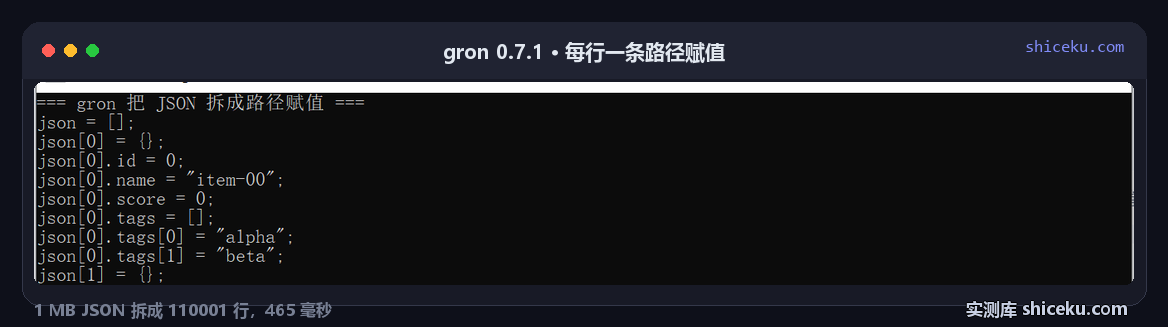
10000 records produce 110001 lines, which is 11 per record. Each record contributes a line for the object itself, one per scalar field, and one per array element in its tags list.
Every line is a path assignment
The output starts with json = [];, then json[0] = {};, then json[0].id = 0;. Each value gets its full path spelled out, which is exactly what a line-based tool needs.
Flattening takes 465 ms
The forward pass over 1072296 bytes finished in 465 milliseconds and exited 0. That includes reading, parsing and writing 2790097 bytes of output.
| Direction | Time | Output |
|---|---|---|
| JSON to lines | 465 ms | 2790097 bytes |
| Lines back to JSON | 24094 ms | 1852299 bytes |
52 times slower backwards
24094 divided by 465 is 51.8. Going from lines to JSON costs about 52 times what the forward direction costs on the same data, which is the single most surprising number in this test.
The reverse output is smaller
Going back produced 1852299 bytes against the original 1072296 bytes. The extra 780003 bytes are indentation: the reconstructed JSON is pretty-printed, not compact.
Why backwards is so slow
Each line carries a full path like json[9999].nested.deep.v. Rebuilding the tree means re-resolving that path from the root for every one of 110001 lines.
| Pass | Work per line |
|---|---|
| Forward | Append one path segment |
| Backward | Walk from root to leaf, then assign |
Path resolution dominates
Forward work grows with the number of values because appending is constant time. Backward work grows with depth times lines, because every line re-walks its own path.
Deep nesting makes it worse
The test data is four levels deep at most. A document with eight levels would roughly double the backward cost while leaving the forward cost almost unchanged.
What the output is for
Once every value has a path on its own line, ordinary text tools become JSON tools. That is the only reason the format exists.
| Task | How gron helps |
|---|---|
| Find a field anywhere | grep a key name, get its full path |
| Compare two documents | diff the two flattened outputs |
| Pull one value | grep the exact path, cut the value |
| Rebuild after editing | --ungron, at 24094 ms per megabyte |
Diffing is the strongest use
Two JSON files that differ in one nested value produce one changed line after flattening. Diffing the raw JSON would show a whole block rewritten because of indentation and ordering.
Do not use the reverse direction in a loop
24094 ms for one megabyte means a script that round-trips a few files spends most of its time in gron. Edit the JSON directly or use a tool built for it.
Nine flags in 1065 bytes of help
The whole option list fits in 1065 bytes of help text. Nine flags, no config file, no environment variables.
| Flag | Effect |
|---|---|
| -u, --ungron | Turn assignments back into JSON |
| -v, --values | Print only the values, not the paths |
| -c, --colorize | Colour output, on by default for a terminal |
| -m, --monochrome | Force plain output |
| -s, --stream | Treat each input line as its own JSON object |
| -j, --json | Emit a JSON stream instead of assignments |
| --no-sort | Skip sorting, documented as faster |
| -k, --insecure | Skip certificate checks on a URL input |
| --version | Print the version string |
Colour is decided by the terminal
The help says colorize is the default on a tty. Redirect the output to a file and the escape codes disappear automatically, so a plain run is safe to store without adding -m.
--values throws away the paths
With -v the output is one value per line with no path prefix. That is the flag for extracting data, while the default form is the one for locating it.
Where it fits
Searching an unfamiliar API response for a field name, or diffing two configuration dumps that are supposed to be equal.
| Task | Fit | Why |
|---|---|---|
| grep across nested JSON | High | Shape is unknown, gron spells every path |
| Diffing two documents | High | One change becomes one changed line |
| Round-tripping files | Low | 24094 ms backwards on 1 MB |
| Editing JSON in place | Low | No editing model, only text lines |
It is a viewer with a side exit
The forward direction is fast enough to use every time. The reverse exists so the format is not a dead end, not so you build pipelines on it.
Licence and cost
MIT. Free for personal and commercial use, source on GitHub, written in Go. The Windows build is one exe with no installer and no registry writes.